

Text to video
Turn a written scene into motion by specifying the subject, action, camera, lighting, timing, and sound.
Save with annual plans 90% OFF All Models · Ends Oct 31Annual plan savings 90% OFF All Models · Ends Oct 31 (Yearly Plans)
 Flux
 GPT Image
 Grok
 KlingMiniMax
 Nano BananaPixVerseQwenRunway
 SeedanceSeedreamVeo
 Wan
Compare multiple leading video and image models, keep prompts and references together, review generation costs, and choose the right model for every project.
A vertical city-and-ocean action shot with fast downhill motion, stylized color, and short-form energy.
Use this promptTurn food or product details into a close-up social video with splash motion, texture, and appetizing light.
Use this promptCreate calming vertical nature footage with flowing water, green foliage, flowers, and soft sunlight.
Use this promptAnimate a branded beauty card or package reveal for ads, creator posts, and campaign teasers.
Use this promptA warm lifestyle moment with champagne, ocean light, and cinematic social-video pacing.
Use this promptIndependent multi-model AI studio
Start with a prompt or reference image, choose the available settings, and test the shot before increasing duration or quality.
Compare multiple leading video and image models, keep prompts and references together, review generation costs, and choose the right model for every project.
Describe the video you want to createFluxGPT ImageGrokKlingMiniMaxNano BananaPixVerseQwenRunwaySeedanceSeedreamVeoWanMulti-model creative workflows
Choose the workflow that matches your source material, compare supported models, direct the result, and review available output settings before generating.
Turn a written scene into motion by specifying the subject, action, camera, lighting, timing, and sound.
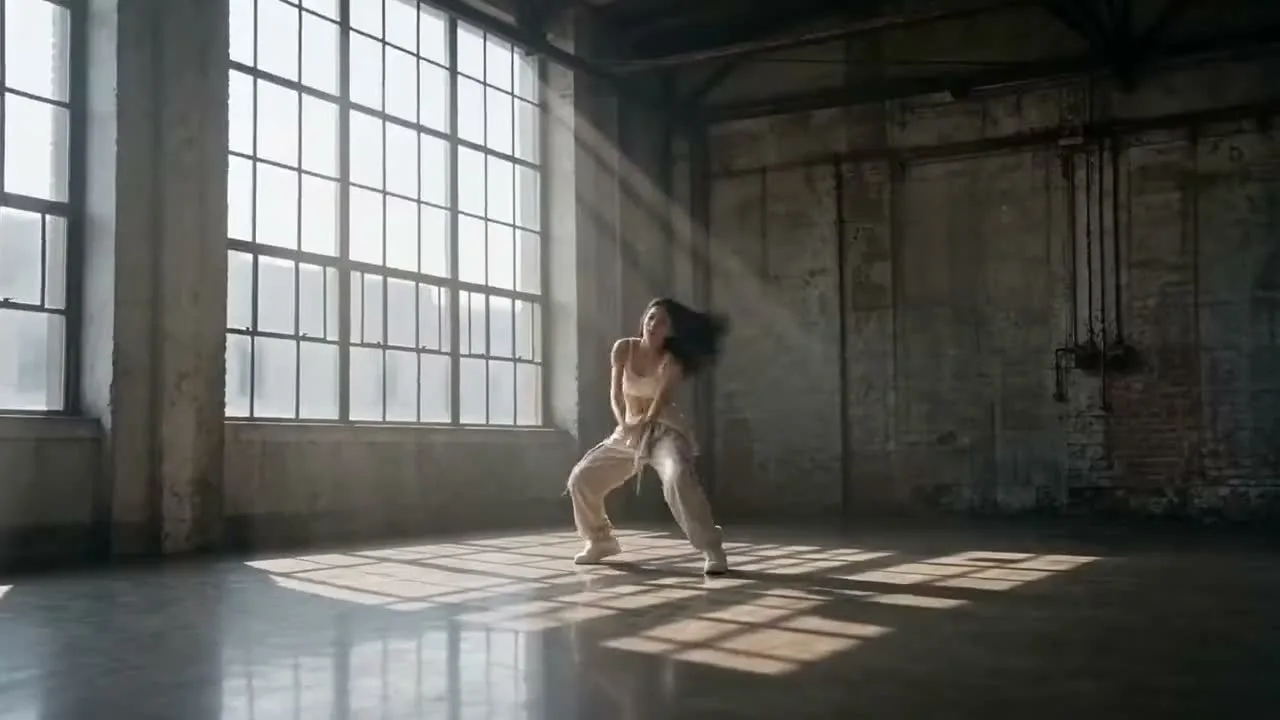
Use a reference image when identity, product details, composition, or art direction should remain recognizable.
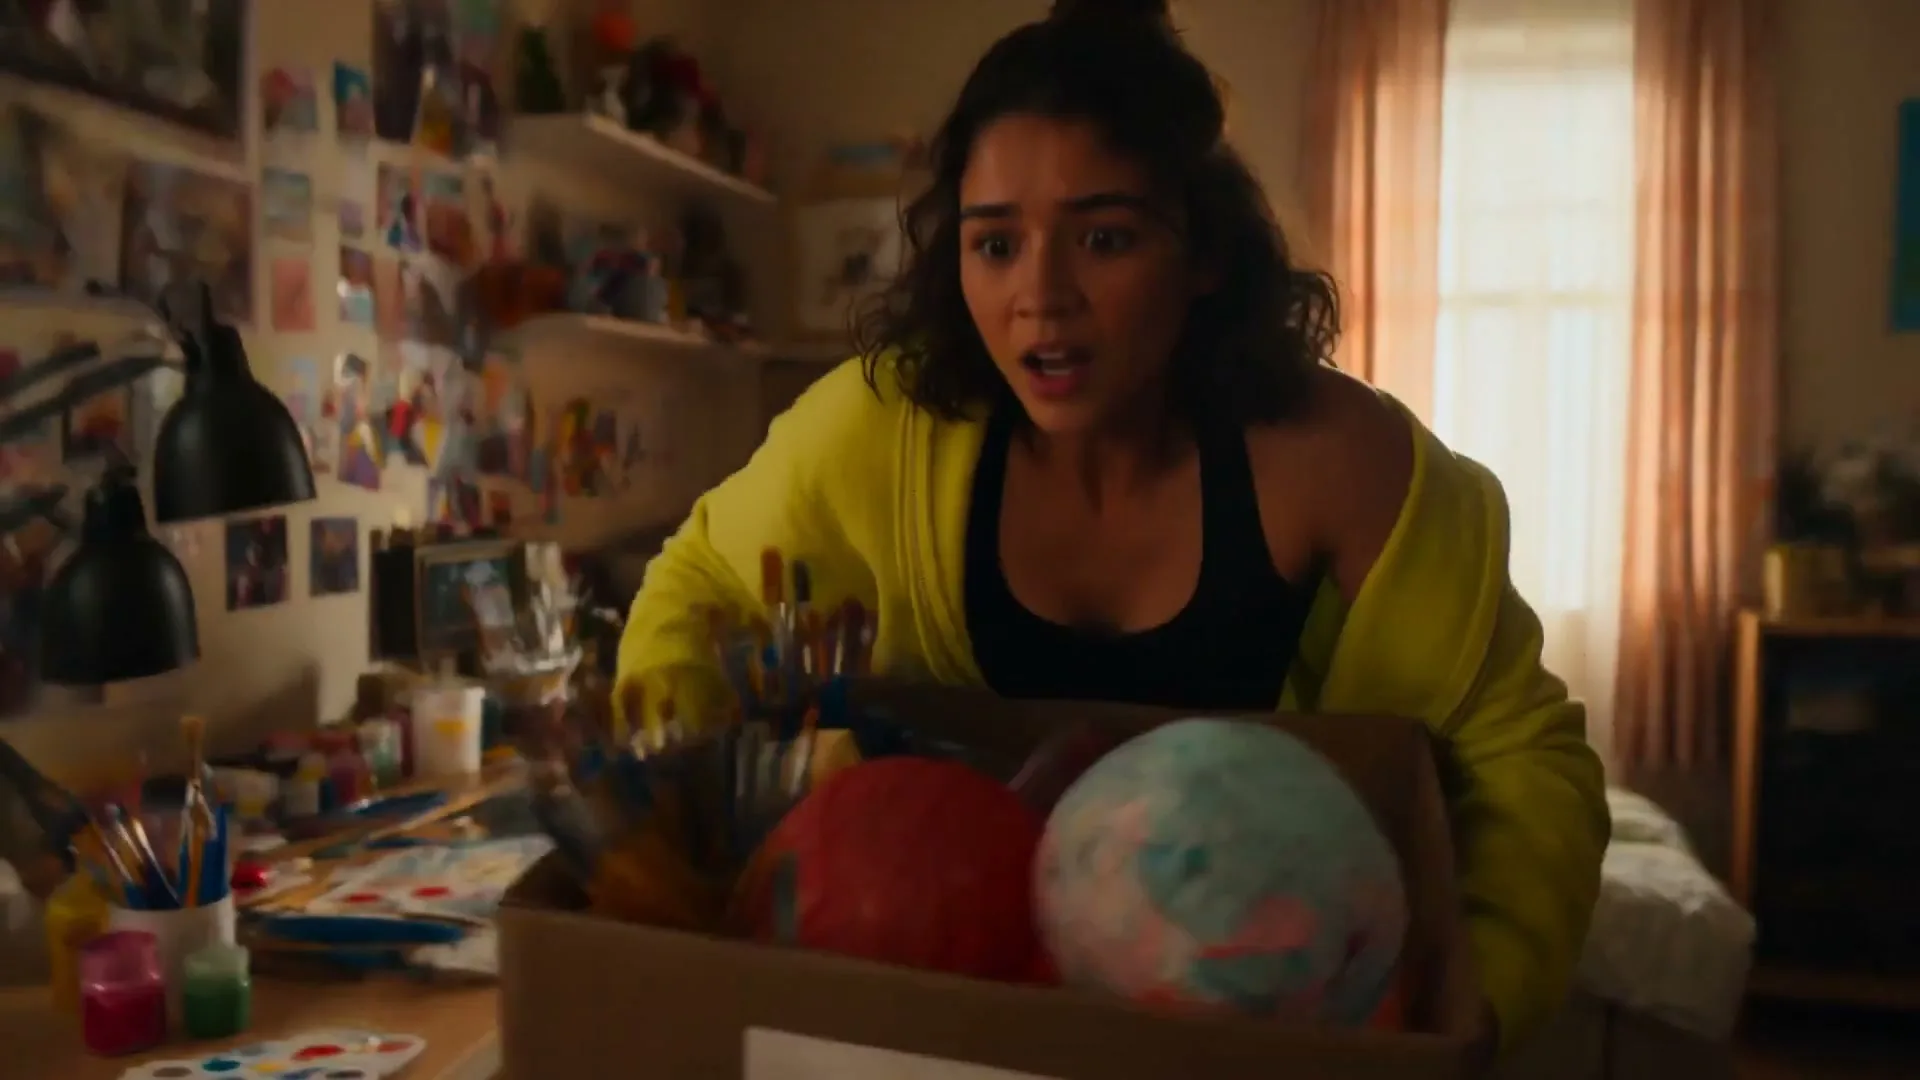
Combine supported image, video, and audio references with text, and state what each asset should control.
Review the model, input mode, ratio, duration, resolution, audio option, and credit cost before generation.
Examples and prompts
Each example isolates a useful creative decision—subject movement, camera direction, lighting, pacing, or sound—so you can adapt the idea instead of copying generic marketing text.
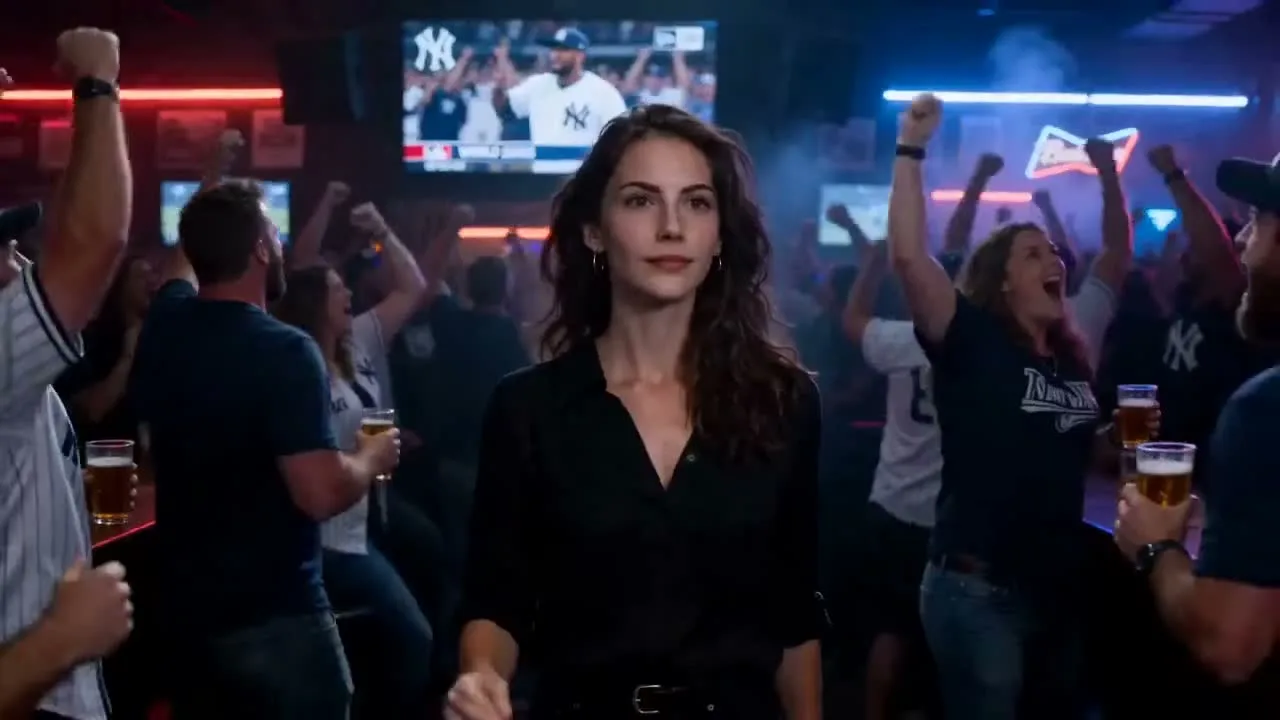
A text-to-video scene with neon bar lighting, suspended motion, and a snap-triggered return to full celebration.
A product still becomes a polished AI video reveal with a camera push, glow, studio reflections, and commercial-ready motion.
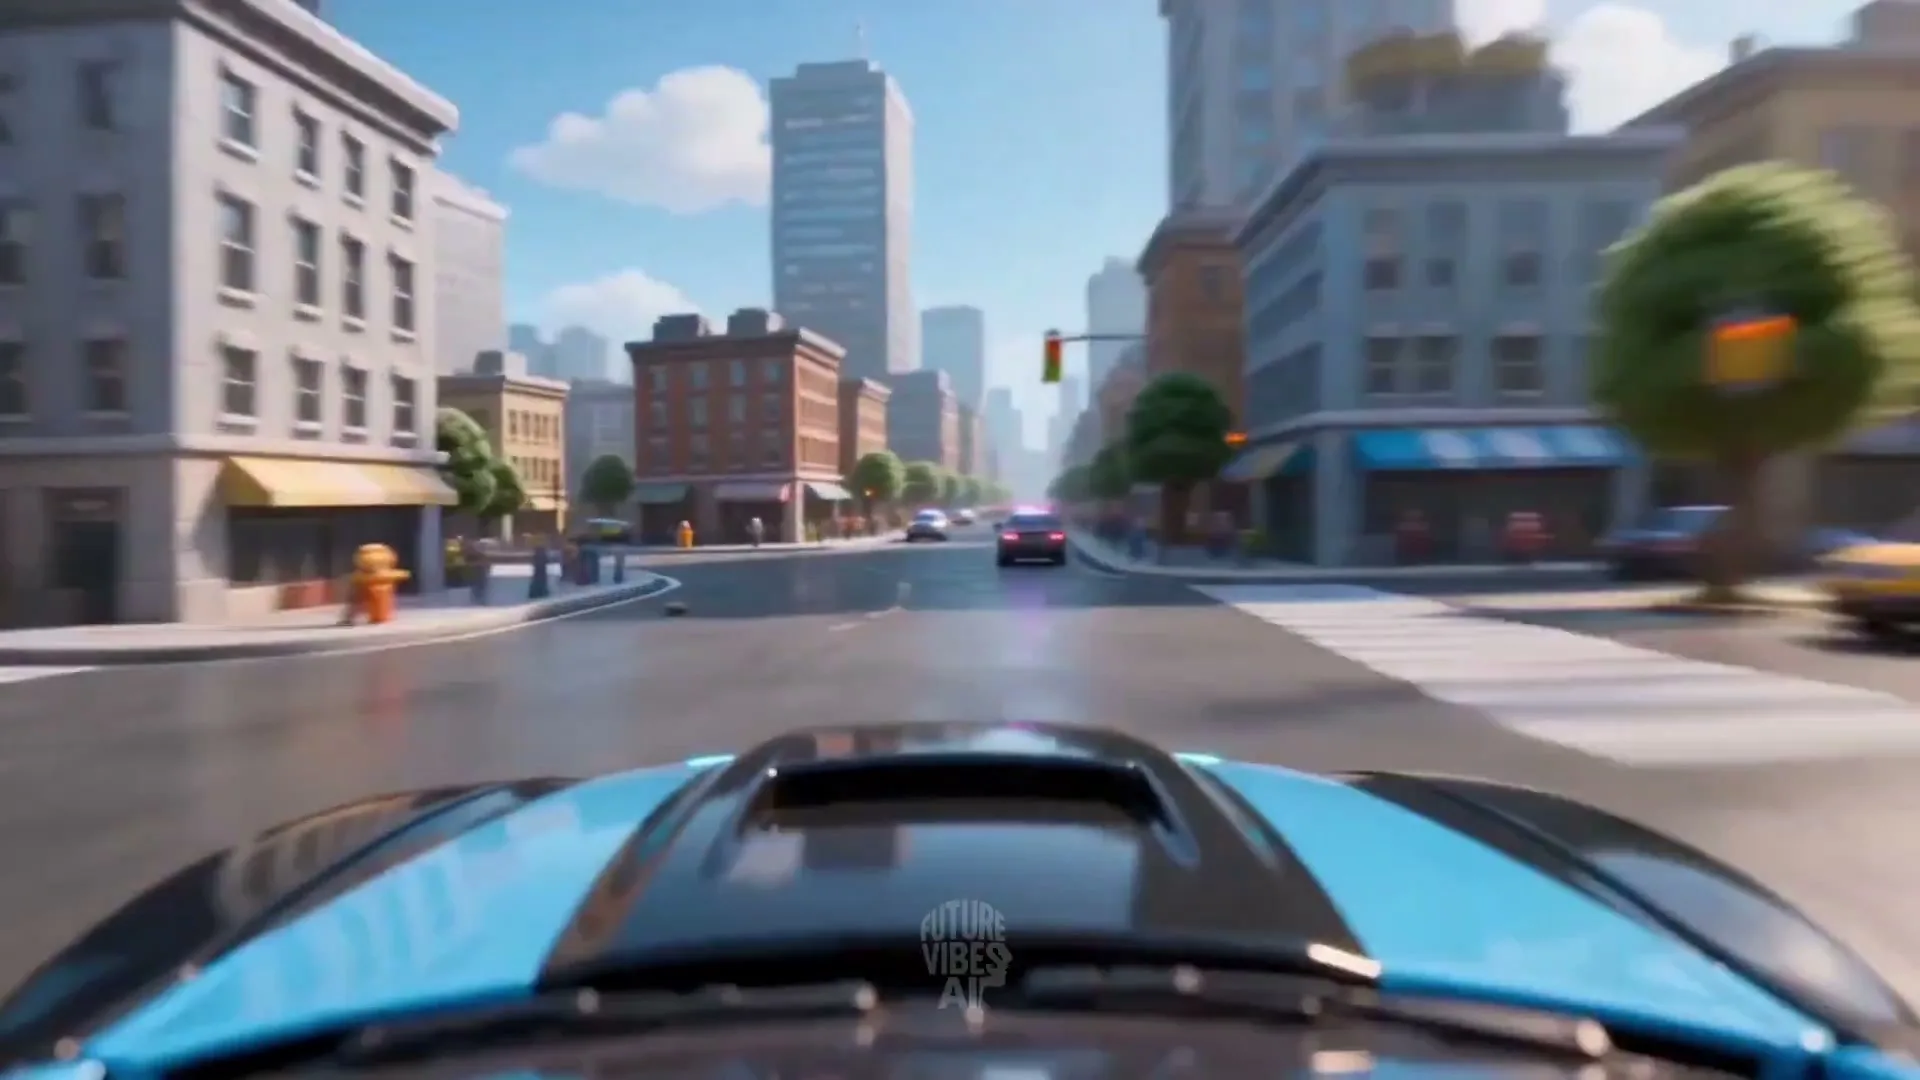
Fast camera moves, playful effects, and a vertical composition turn a simple toy scene into a short-form action sequence.
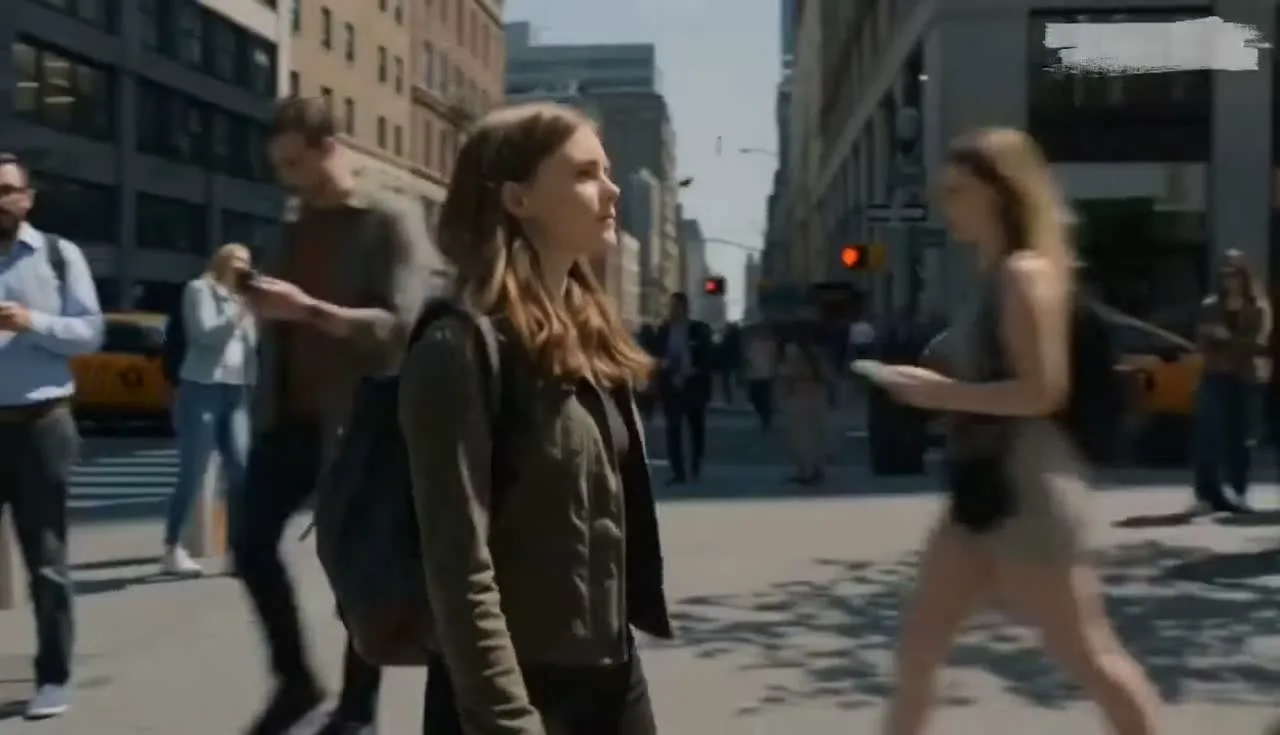
A cinematic prompt where a daylight city scene freezes into silence, then restores motion with a reverse shockwave.
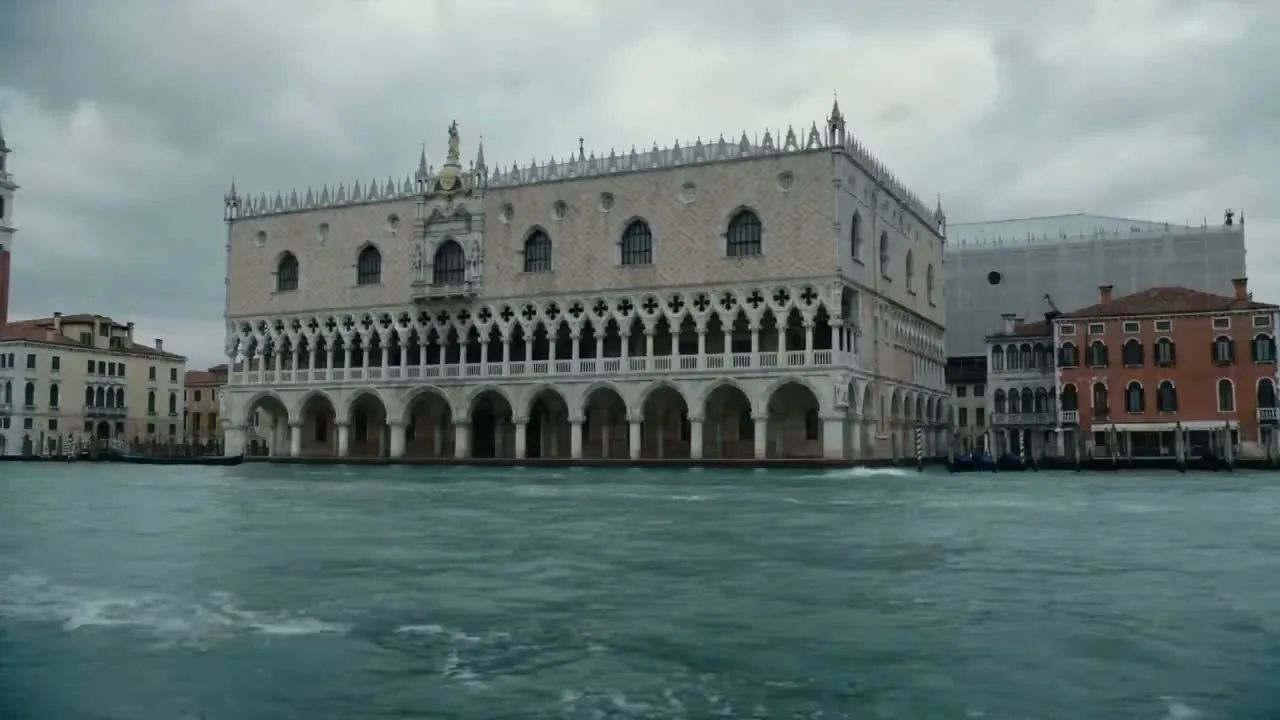
A surreal AI video reveal over historic architecture, built to demonstrate water, scale, and dramatic camera movement.
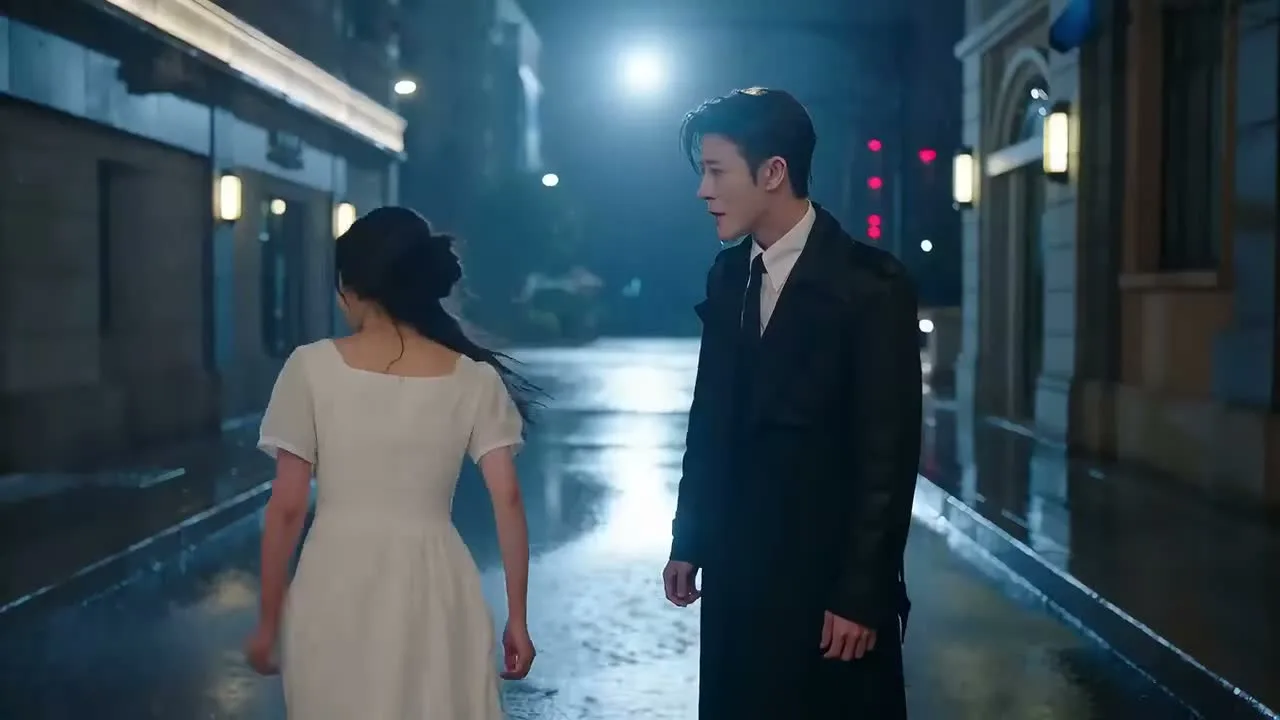
A story clip sequence with rapid cuts, close-ups, expressive lighting, and a creator-friendly narrative arc.
FAQs
Answers about supported AI models, generation workflows, reference assets, audio, usage rights, plans, and production timing.
Seadanse is a unified browser workspace for AI video and image creation. It brings supported video and image models, generation settings, assets, and finished tasks into one workflow so you do not need a separate tool for every model.
The current catalog includes supported models from Seedance, Seedream, Veo, Wan, Kling, Grok, Nano Banana, Flux, and other families shown in the model selector. Available versions and controls can change with provider support, so the generator is the current source of truth.
Seadanse combines video and image models in one workspace, with consistent generation controls, one account, centralized task history, and plan-based access. You can switch models without rebuilding the rest of your workflow.
Supported Veo modes can generate video together with synchronized dialogue, sound effects, or ambience. Audio availability depends on the selected Veo version and settings displayed in the generator.
Yes, when the selected model supports multi-reference input. Reference limits and accepted media vary by model, so the upload controls shown after you select a model define what that workflow accepts.
Seadanse does not claim ownership of your generated output. Commercial use depends on your plan, the selected model's terms, and your rights to prompts and uploaded assets; you remain responsible for lawful use of the final content.
Yes. Run the same creative brief with different supported models and review the completed results in your creation history. Model controls and credit estimates remain visible before each run so you can compare quality, speed, and cost.
Seadanse supports professional workflows for marketing, social content, product visuals, client drafts, and production tests. Paid plans add private generation, watermark-free supported outputs, higher concurrency, and commercial-use workflows as listed on the pricing page.
Timing varies by model, queue load, duration, resolution, audio, and reference complexity. Short jobs often finish within a few minutes, but the task status in your creation history is the reliable indicator for each run.
Choose text-to-video or image-to-video, select a supported model, describe the scene and motion, review duration, resolution, sound, and credit cost, then submit the generation.
Compare the same short brief across models. Look at input support, motion style, prompt adherence, duration, sound, speed, and credit cost for the specific shot you need.
Seadanse includes API-key management for supported integrations. Available endpoints and models vary by plan and provider, so confirm the current options in your workspace before building an integration.
New accounts can use any starter credits currently offered to test supported workflows. Access is limited rather than permanently free, and cost depends on the selected model and settings.
Some plans include fair-use access to eligible model tiers. Premium models and certain settings can still require credits; review the pricing table and checkout terms for current limits.
Generation time varies by model, mode, duration, resolution, references, queue demand, and provider status. The workspace shows the current task state while your result is being created.
Choose a supported model, add a prompt or reference asset, review the settings and credit estimate, then generate in the same creative workspace.